
A dashboard does not improve how a business runs. It shows data, but it rarely tells anyone what to do next. The real gains come from giving people context, capturing data without adding friction, and focusing on the few signals that matter for a specific decision. That is the central lesson from a recent conversation on manufacturing, AI and product leadership.
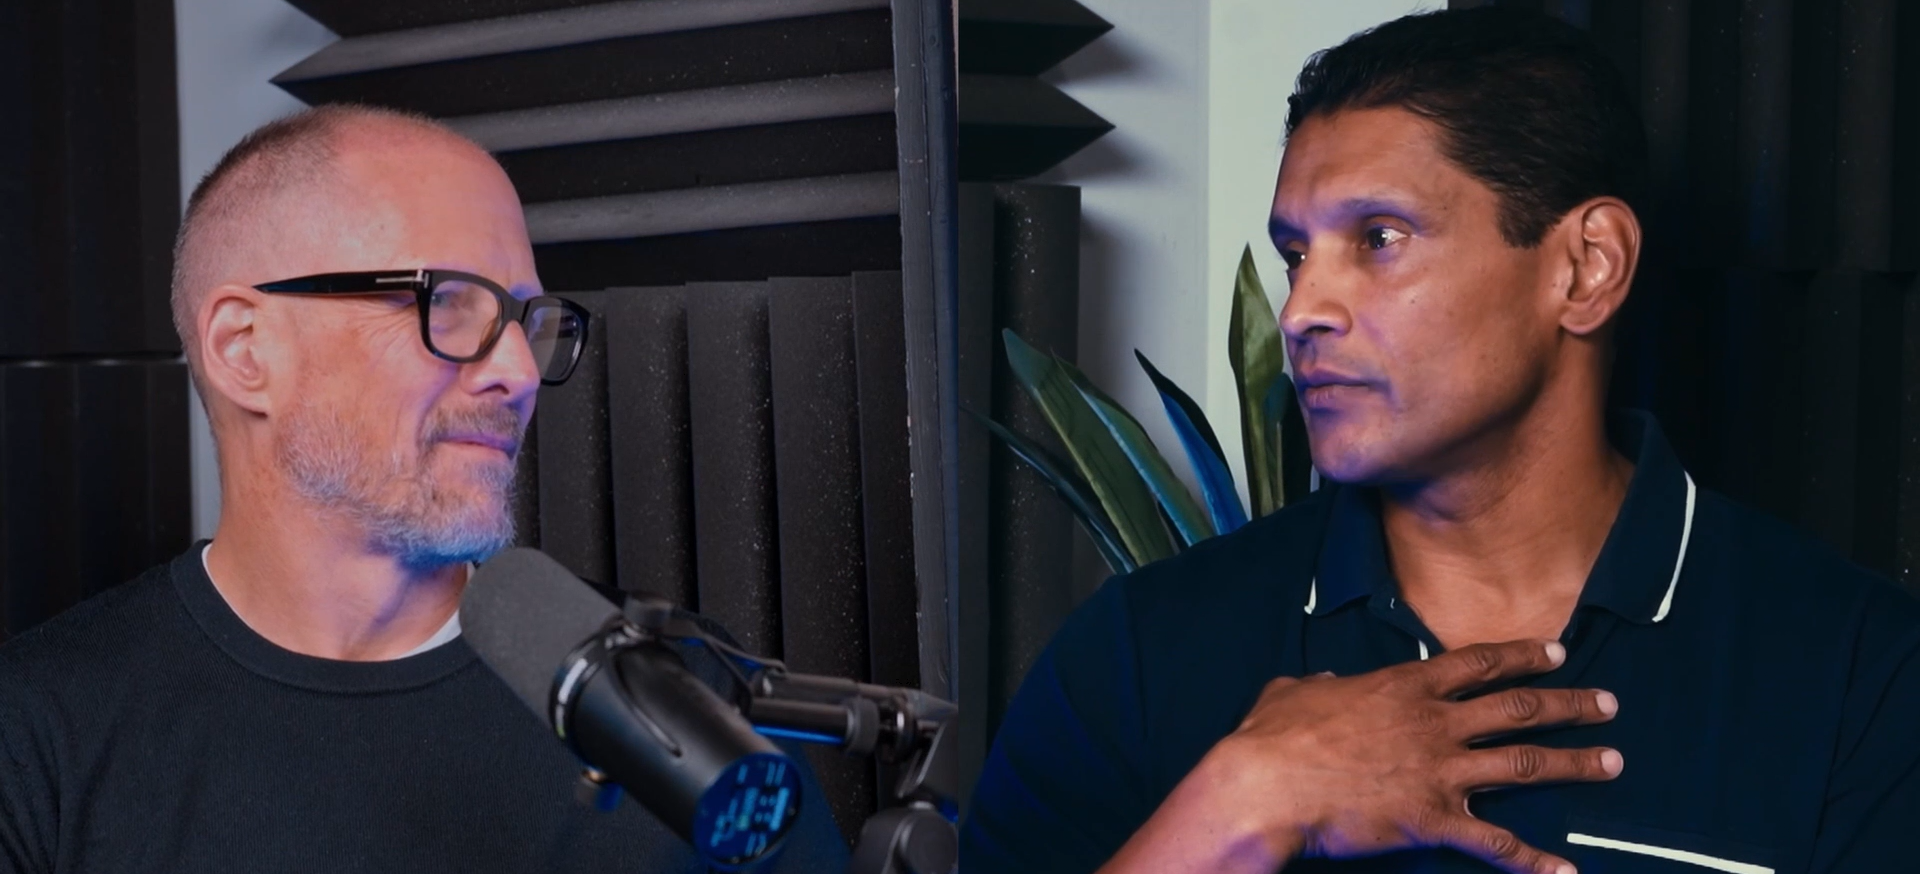
In Season 2, Episode 11 of CTO2CTO, Forte Group CTO Lucas Hendrich spoke with Piyum Samaraweera, Chief Product Officer at L2L. The name stands for "leading to lean", a nod to the lean manufacturing principles the company grew out of. L2L connects plant operations into a unified data layer, so that plants can recover from downtime faster and leadership can deliver orders on time and protect margins.
The setting is a factory floor, but the lessons apply to any organization that has invested heavily in data and is still waiting for better decisions.
Samaraweera points to a decade of manufacturing technology spending, roughly 2000 to 2015, that ran into the billions. National productivity figures did not rise to match it. Much of that money went into collecting data, and much of the data ended up on dashboards. He calls the result the dashboard fallacy: the belief that having a dashboard means the operation will run better.
His explanation is simple. An infographic is a pretty picture, and many dashboards are the same. People look at them and nothing changes, because the person viewing the data lacked the context, and the software, without that context, could not recommend a decision.
Generative AI changes this, in his view, because it helps combine what happened with why it happened. Hendrich added that user expectations are shifting too. People no longer want a standard dashboard. They want to ask a question in plain language and get back the correlation, the explanation and the story behind the numbers.
Samaraweera noted that his users were asking for exactly this 20 years ago. It could have been built then, but at a cost that made no sense. Two things have changed since. Building it is now far easier, and people use ChatGPT and Gemini in daily life. Once natural language works in consumer technology, business users expect it at work as well.
A typical plant runs several purpose-built systems for manufacturing, maintenance, quality and workforce. Each works well on its own, and each is a data silo. Samaraweera warns that simply connecting the silos is not enough, because the context lives at the edges where they meet, and those edges are human. The operator, he says, is still the secret sauce on a production line, because the operator knows how the machine runs best.
That creates a hard product problem. Much of the data in a plant has always been entered by people, through checklists and changeover forms, in keeping with the lean tradition of the Gemba walk, where supervisors go to the line to see the work and talk to the people doing it. But paper and manual entry invite pencil whipping, where a form gets filled in without the check really happening. And software cannot interrupt an operator mid-task to ask what they are doing.
L2L's answer is to keep lowering the bar for getting data in:
The principle reaches beyond manufacturing. Samaraweera frames every feature as a job to be done, and in a plant the rule is blunt: if the software asks an operator to do extra work, it has already failed. Better data quality comes from a lighter burden, not from more fields.
L2L's direction is to move from surfacing data, to making recommendations, and eventually to making decisions. Samaraweera is clear that the company is still mostly in the recommendation phase, and that the last step has to be taken carefully. A plant cannot be taken offline to test an idea, and an operator distracted at the wrong moment is a safety risk.
His test is whether a decision is deterministic or probabilistic. For probabilistic outputs, he wants confidence close to 99 percent before software acts on its own. The likely path is to find specific workflows where confidence is high, let AI surface what matters, and use deterministic logic to make the actual call. Hendrich drew the same line for construction, where a small calculation error can have outsized consequences: the harness around the model matters as much as the model.
Two more ideas shape how L2L thinks about this:
This also reframes the goal. L2L has never aimed to eliminate downtime, which Samaraweera calls a fallacy of its own. Machines will go down. The goal is to get the right people to the machine and recover as fast as possible.
AI has made data much cheaper to process. Samaraweera described a recent request from a customer who wanted to know how AI was being used in the product. Ten years ago, answering it would have meant asking an engineer for hours of help writing SQL queries. This time he combined product analytics, database data and HubSpot call data in about ten minutes. Most of that time went into deciding what he wanted to see.
The risk is that cheap processing leads to more data and more content, not more value. Teams collect everything and then mine it for meaning, and a two-paragraph answer comes back as five pages that nobody wants to read. His remedy is to work backward:
Hendrich described this as a shift in scarcity. When software can produce a hundred times more features or content, human attention becomes the limit, and the real question is whether the output improves anything.
In manufacturing, the core KPIs have not changed: deliver the order on time, at the right quality and margin. New ones are emerging, though. Samaraweera singled out energy consumption, as power costs rise, as a measure many manufacturers had not focused on before. He also sees AI lifting plant-level data to the enterprise level. That can support corporate decisions such as how to standardize processes across sites or roll out the next plant, and can give continuous improvement teams proof of whether new processes are working across 10 or 15 plants.
The conversation was candid about the limits of this approach.
Hendrich opened the episode with an observation Forte Group sees across its work: product is shifting left. As generative AI makes building software easier, the hardest thinking moves to deciding what to build. At L2L, designers now create code in a production branch.
Samaraweera describes his role in similar terms. Organizations are never short of ideas. The challenge is making sure everyone is climbing the same mountain, so that each team can see how its work connects to the product, go-to-market and corporate strategy. His working method is the scientific method: state the problem, list the assumptions, and test them, because an assumption is not true until it has been tested.
That is why many of Forte Group's engagements now begin with practices that are not new, such as asking the five whys and mapping the value stream. The technology is increasingly the easy part. The hard part is choosing the right problem and confirming that solving it makes a real difference, whether on a plant floor or in a software organization.
Watch or listen to the full episode: CTO2CTO S02E11 with Piyum Samaraweera. The conversation also covers lean manufacturing culture, training the next generation of veterans when AI guides more decisions, and what a chief product officer actually does.
Explore more episodes: CTO2CTO podcast


83% faster delivery. Under 10% rework. See exactly how Xceptor got there.